Showing posts with label bash. Show all posts

Exit Shell script with error if any command fails


I wrote a Bash script today to automate my code review process and I noticed that even when certain commands in the workflow fail, the script still executes the remaining commands.


For example, let's say I have two commands that run synchronously:


git merge origin/dev git tag <new-tag>


In this case, if the `git merge` command fails due to some reason, it will still create a new tag, which is not my intended workflow.


To avoid this, if any of the commands returns a non-zero exit status, the script should break and exit. This can be achieved in Bash by using the `-e` option.


Add the following at the very top of your script (below the shebang line):


#!/bin/bash set -e


This will enable the `-e` option for the entire script.

If you only want to enable this option for specific commands, you can prefix them with `set -e`, like this:


set -e git push


This will cause the script to exit if the `git push` command fails.


Updating Whiptail gauge (Progress bar) with Python

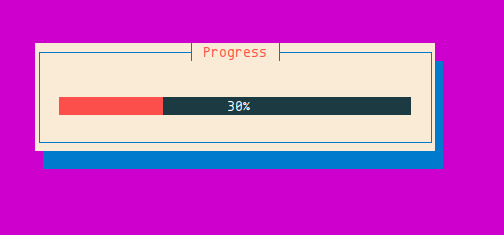
I spent last week writing a Python script to create an installer for some services, and I wanted to show the installation progress using a gauge. So I used the whiptail utility which comes with most linux distros as it was easier to use for this particular task. However, there was one caveat, that it reads the progress value from the standard input. It was a bit tricky and took me bit of a time to figure it out...but this is how to do it.

It's mentioned in the manual.

--gauge text height width percent
              A gauge box displays a meter along the bottom of the box.  The meter indicates a percentage.  New percentages are read from standard input, one
              integer  per  line.  The meter is updated to reflect each new percentage.  If stdin is XXX, the first following line is a percentage and subse‐
              quent lines up to another XXX are used for a new prompt.  The gauge exits when EOF is reached on stdin.

Whiptail is a bash utility so we have to call the bash command within our python script. I used subprocess module to do that. Since we have to input the progress values to the command using the standard input, we have to set it's stdin to subprocess.PIPE. Whiptail will print to the stdout, so we don't really have anything to do there (means, it will read from the stdin and display the progress accordingly.)

#!/usr/bin/env python

import subprocess
import time

process = subprocess.Popen(["whiptail", "--title", "Progress", "--gauge", "", "6", "50", "0"], stdin=subprocess.PIPE)

for i in range(0,101, 10):
    time.sleep(1)
    process.stdin.write(b'{}\n'.format(i))
    process.stdin.flush()


So this is it. If you run this script, you will see the progress bar updates and reflects the new progress nicely.


Updating Whiptail gauge (Progress bar) with Python


One thing to note here is that you may have seen in many places that they don't recommend to use stdin.write directly due to deadlocks etc, and ask to use communicate(input="") method. But it's not definitely going to work here as the communicate(input="") method is going to write to the stdin and waits for the process to exit. That way we won't be able to keep updating the progress bar. That was from my understanding, but I might be wrong. If you know any better way to do this, or to use communicate(input="") instead of stdin.write(), feel free to leave a comment and let me know.


Bash - Switch STDERR to STDOUT


Bash Switch STDERR to STDOUT

Today I wrote a bash script to create a very simple porcelain client on Git to add and commit files without entering all the git add, commit commands. I personally don't like to use Git clients with GUIs because they are somewhat complex, and I really love working on the terminal and the comfort of typing on my keyboard. But typing all the commands every time when working with Git isn't productive as well. So I decided to create a small client so I can just run it and do all the basic repetitive tasks through it.

Since I wanted to run it in the terminal and also to reduce the usage of mouse, I used whiptail to generate all the UIs inside the terminal to select files and commit. However, while working with it, I noticed that some components of whiptail, like checklist, for example, uses STDERR to return its output. I have no idea why it prints the output on STRERR, but I wanted it to print to the STDOUT. So here's how to do that redirection.

You just have to add the following at the end of the line you need.

3>&1 1>&2 2>&3
Example:

whiptail --separate-output --title "Select files to add" --checklist " " 10 60 5 '$filelist' 3>&1 1>&2 2>&3

What it does?

Well, I hope you already know what are file descriptors. If not, basically there are three of them,

0 - STDIN
1 - STDOUT
2 - STDERR

in addition to these specific FDs, there are 3-9, and they can be created as we want. In the above line, what we actually do is,

3>&1 = we create a new file descriptor 3, and points it to the STDOUT (& sign is used to refer to another FD, and here we actually create a temporary FD 3 to hold the STDOUT).

1>&2 = Then we redirect the STDOUT to STDERR. We actually needed the above line because we switch it here, and if not for the above, we would lose the reference to STDOUT after the switch.

2>&3 = Now we simply redirect the STDERR to the FD 3 we created, which is currently redirected to the STDOUT.

Now you see that we have switched STDERR to STDOUT and vice versa :) I hope this is clear and will be helpful to someone. I only wanted to write this here so I can refer to it on a later day in case I forget. But if you ever come across this post, don't forget to leave a comment.

Ubuntu touch: Change the created or modified date of a file using terminal.

Ubuntu touch: Change the created, access or modified date of a file using terminal.


Last week I wrote an automation script, which (a part of it) generated some files, and I wanted to store them for a maximum of three days. So along with the script, I wrote another bash script to delete any files which are older than three days, and I set it to run as a cron job.

After writing all the scripts, I wanted to test whether they work. For tests, I needed some files which are at least three days old and useless at the same time because my script will be deleting them.

So how did I do that?

I believe you all know about the touch command. What does it actually do? Well, I'm sure most of us will say "we use it to create a file". It's true. But that's not what touch command does. Its real purpose is to change the access and modification time of a file. It will create a new file only if it doesn't exist ;) So this blog post is about how to do it. I thought of sharing it in my blog for my own reference as well as a help for those who will be looking for it in the future ;)

In the touch's manual page, it says:

Update  the  access  and modification times of each FILE to the current time.

A FILE argument that does not exist is created empty, unless -c  or  -h
is supplied.

A  FILE  argument  string of - is handled specially and causes touch to
change the times of the file associated with standard output.

Mandatory arguments to long options are  mandatory  for  short  options
too.

So, that's it. You just have to add the -d parameter and pass in a timestamp and it will create the file with given date / time. If the file already exists, it will modify the access / created time to the given one. Too easy right? For my specific requirement, the following command was enough for me.

touch -d '4 day ago' test.txt

As you can see, the value given to the -d parameter could be a human friendly syntax like shown above. You can also pass in a timestamp if you wish. Please read the manual page for more information on that.

I hope this will be helpful for someone :)

Convert putty ppk key file to public, private key pair to use in SSH client Ubuntu

Convert putty ppk key file to public, private key pair to use in SSH client Ubuntu


Today, a friend asked me to login to a Linux server and he sent me a PPK file which he uses with his Putty client in Windows. I had to generate a Public / Private key pair from that PPK file in order to use it with my SSH client in Ubuntu. It was really easy and took me only a few minutes. I thought I should post this in my blog so it would be helpful to somebody, and it would also be useful to me as a quick reference in future whenever I need it again.

This is how to convert your PPK file to an OpenSSH keypair.
  1. First, if you don't have putty tools installed in your computer, you have to install it. This will help us when dealing with PPK files.

    sudo apt install putty-tools
  2. Now we can use the puttygen utility to generate an OpenSSH private key from this ppk key file. To do that, run the following command.

    puttygen <your-key-file>.ppk -O private-openssh -o <new-key-file>
    Ex: puttygen key.ppk -O private-openssh -o id_rsa
    Here the -O option stands for "output-type" and it specifies the type of file we want to generate. By giving it as "private-openssh", we tell it to generate an OpenSSH private key file. You can see the manual page by running man puttygen if you want to learn more about the other output types. (But they aren't required now).

  3. Okay, now we have the private key. We can use ssh-keygen to generate the relavent public key for this private key file.

    ssh-keygen -y -f <new-key-file> > <new-key-file>.pub

    Ex: ssh-keygen -y -f id_rsa > id_rsa.pub

    Here the -y and -f options mean the following: (taken from the Manual page)

    -y = This option will read a private OpenSSH format file and print an OpenSSH public key to stdout.
    -f filename = Specifies the filename of the key file.


    I hope it's clear. We are almost done.

  4. Last step is to set the right permissions for the new key pair. Usually, the SSH client expects the Key files to have permission as 400 or 600. So let's set it.

    chmod 400 id_rsa
    chmod 400 id_rsa.pub
    Now we should be able to login to our server using the new key pair we generated.

    ssh -i .ssh/do_server/id_rsa root@xxx.xxx.xxx.xxx

I hope this will be useful to somebody in future :) If this post helped you, don't forget to leave a comment and let me know !

Change prompt in Ubuntu terminal - Hide hostname and working directory.

Oftentimes, I use Tmux to split my terminal windows to save time from switching between them. Although that was quite nice and useful, I always had one problem when working inside some directories located deep down my directory hierarchy. That is, whenever I split up my terminal, I'm always left with a small window for each terminal. So when I'm inside the deeper directories, the prompt takes much longer space to show the path and my prompt was always kept at the end of the window. That was really inconvenient.

Here's how it looked like:

Change prompt in Ubuntu terminal - Hide hostname and working directory.

I came up with this solution to get rid of that problem. I decided to change my prompt so it would only show my username and current directory instead of the full path. That would make my prompt very shorter and hence I would have enough space to type in my commands and see it all clearly. I was a little bit concerned about this as I still wanted to see my host name whenever I'm connected to a remote server through ssh because I often connect to multiple servers at once so it's important to see which server I'm in before running any commands. Anyway I realized I could make this change available only for my local user account so the usual prompt will be available to me whenever I'm connected to a ssh session.

Here's how to do that.

First edit your .bashrc file in your home directory.

vim ~/.bashrc
Locate the following code block.

if [ "$color_prompt" = yes ]; then
    PS1='${debian_chroot:+($debian_chroot)}\[\033[01;32m\]\u@\h\[\033[00m\]:\[\033[01;34m\]\w\[\033[00m\]\$ '
else
    PS1='${debian_chroot:+($debian_chroot)}\u@\h:\w\$ '
fi

You need to change the PS1 line to change the prompt. By default it is in username@host:workingDirectoryPath format. Here's how I have changed them.

if [ "$color_prompt" = yes ]; then
    PS1='${debian_chroot:+($debian_chroot)}\[\033[01;32m\]\u:\[\033[01;34m\]\W\[\033[00m\]\$ '
else
    PS1='${debian_chroot:+($debian_chroot)}\u@:\W\$ '
fi

If you notice well, you will see that I have removed the h and replaced w with W (which means hostname is removed and the full directory path is replaced by the current directory).

Save the file and quit vim.

Now we need to reload the bash configuration for our current terminal session. Just run the following command to load your new configs.

source ~/.bashrc
Once you run the above command, you should immidiately notice that your prompt is changed :) But now you won't see the full directory path in your prompt. You can still see it by running the following command.

pwd
Here's how it looks now.

Change prompt in Ubuntu terminal - Hide hostname and working directory.

That's it !! I hope this will be useful to someone. Please feel free to comment and let me know if I have missed anything or if you know a better way to do this.

Download a list of files using a shell (bash) script.

Download a list of files using a shell (bash) script.


Today I'm going to share something interesting which will help you to download a large number of files at once. For one of my projects, I had to find images from Google, and upload them one by one to a particular website and create posts. At first, this was not much difficult as the number of images I needed was very little. But it kept growing and growing and I had to manually do the same thing repeatedly. Since I'm a lazy person by nature, I wanted to automate the process and here is a part of it, which I did to download the images quickly.

Unfortunately I couldn't automate the Googling part because it needed some human eyes to find quality images (I didn't want to go to the level of automation using computer vision ;) ). So however I searched for images, then whenever I found an interesting image, I right clicked on it and opened the image in a new tab (using ctrl + click). I kept doing this until I had enough images.

Here's the interesting part:

I installed this awesome Firefox extension in my browser, which allowed me to copy all of the URLS which were currently open in my brower. That was very convenient given that I had to copy each URL one by one when I began this task.

So now I have a list of URLS of the images I wanted to download. Now what? I pasted the copied list to a text document and opened another text document to write my shell (bash) script. So here it is.

#!/bin/bash

file="urls.txt"

while IFS= read line
do
    echo "$line"
    wget "$line"   
done <"$file"

Explanation: First I assign the name of the file I want to read into the file variable. Then I simply read the file line by line and run a wget command with the url to download the file.

To run this script, all I had to do was fire up a terminal, grant the execute permissions to the file and run it using the following command.

$ ./download.sh

download.sh is the name of your shell script.

That's it folks. I hope this will help someone :) Please leave a comment if you think this helped you or if you think I miss anything.

Fix libQt5Charts.so.5: cannot open shared object file error with Redis Desktop Manager in Ubuntu


A few days ago, I was looking for a Redis client for Ubuntu and found that there is one called Redis Desktop Manager. Although it's free and open source, it only provides builds for Windows. Ubuntu and Mac OS users have to subscribe by making a monthly payment or they can build it by themselves using the source (: So I opted for the second option and built and installed it in my Ubuntu box since it was for a small task.

Then today, when I tried to run the RDM again, I got this error and I was wondering what might have changed in the system. In fact there was nothing changed so I had to dig a little bit more into the error and found why I got this error. So here's how I fixed it.

If you haven't built the Redis Desktop Manager (RDM) by source before, this is how to do it. (It's all well documented)

~$ git clone --recursive https://github.com/uglide/RedisDesktopManager.git -b 0.9 rdm && cd ./rdm

~$ cd src/
~$ ./configure
~$ source /opt/qt59/bin/qt59-env.sh && qmake && make && sudo make install
~$ cd /usr/share/redis-desktop-manager/bin
~$ sudo mv qt.conf qt.backup

Now it's done and you can simply run RDM by entering the command:

~$ cd /usr/share/redis-desktop-manager/bin/
~$ ./rdm

or simply by using:

~$ sh /usr/share/redis-desktop-manager/bin/rdm.sh
I believe that you are reading this blog post means you got either of the following errors when you run the above command:

/usr/share/redis-desktop-manager/bin/rdm.sh: 2: /usr/share/redis-desktop-manager/bin/rdm.sh: source: not found
/usr/share/redis-desktop-manager/bin/rdm: error while loading shared libraries: libQt5Charts.so.5: cannot open shared object file: No such file or directory

or just:

./rdm: error while loading shared libraries: libQt5Charts.so.5: cannot open shared object file: No such file or directory
It says it's unable to load the libQt5Charts.so library. So if you are sure that you have installed (I bet you have) and still get this error, you need to do a few things before running RDM.

First you need to tell it where you have the QT libraries. When you build from the source, the QT libraries are installed at /opt/qt59 directory.

So just enter the command

~$ source /opt/qt59/bin/qt59-env.sh
Now if try to run RDM again, it should work fine :) Since this seems reduntant for us to enter this command everytime we want to run the Redis Desktop Manager, you can edit the rdm.sh file and add the above line on top of it.

Note: If you paid enough attention to the build process, you may have noticed that we ran the above command during building it from the source. That's the reason why it worked a few days ago when I installed it.

So let's update /usr/share/redis-desktop-manager/bin/rdm.sh file.

~$ vim /usr/share/redis-desktop-manager/bin/rdm.sh
#!/bin/bash
source /opt/qt59/bin/qt59-env.sh
DIR=$(dirname "$(readlink -f "$0")")
export LD_LIBRARY_PATH="$DIR/../lib":$LD_LIBRARY_PATH
$DIR/rdm

Notice that we added the line: source /opt/qt59/bin/qt59-env.sh after the shebang. Now save it by pressing ESC then :wq in vim and RDM should load fine :)

I also found that having to enter long paths to run RDM is overkill. So I just added a softlink to my /usr/bin directory using the below command.

ln -s /usr/share/redis-desktop-manager/bin/rdm.sh /usr/bin/redis-desktop
Now I can run Redis Desktop Manager using the redis-desktop command.

That's it folks. I hope this will be helpful to someone. Please don't forget to let me know if I have missed anything, and leave a comment if you know a better way to do this.